Best AI Coding Models Compared: The February 2026 Guide
Claude Opus 4.6, GPT-5.3 Codex, Gemini 2.5 Pro, DeepSeek V3.2, and Qwen3-Coder compared on benchmarks, pricing, and real coding tasks to pick the right model.
Tag
19 articles tagged #Claude.
Claude Opus 4.6, GPT-5.3 Codex, Gemini 2.5 Pro, DeepSeek V3.2, and Qwen3-Coder compared on benchmarks, pricing, and real coding tasks to pick the right model.
A data-driven comparison of Claude Sonnet 4.6 and Opus 4.6 covering benchmarks, pricing, speed, coding performance, and real-world use cases. We help developers choose the right Anthropic model for their needs.
February 2026 packed six AI launches into three weeks: GPT-5.3 Codex, Claude Opus and Sonnet 4.6, Gemini 3.1 Pro, DeepSeek V4, compared on benchmarks and price.
P.04Models that think before they answer are reshaping AI engineering. We break down how extended thinking, reasoning budgets, and chain-of-thought inference work across Claude, OpenAI o3, Gemini, and DeepSeek-R1 — and when you should actually use them.
Most AI agents fail in production. Here are the architecture patterns, error handling strategies, and guardrails we use to build agents that actually ship.
After 90 days of using Claude Code across our entire engineering team, here is what actually changed — the good, the bad, and the productivity numbers.
Claude Sonnet 4.6 matches Opus performance at Sonnet pricing. Full breakdown of benchmarks, features, adaptive thinking, and what it means for developers.
A step-by-step guide to deploying a production-ready AI chatbot with streaming responses, conversation memory, and rate limiting using Claude API and Vercel.
NASA's Perseverance rover used Claude AI to plan its own Mars drive route. Here's the pipeline, verification, and safety layers that made it work.
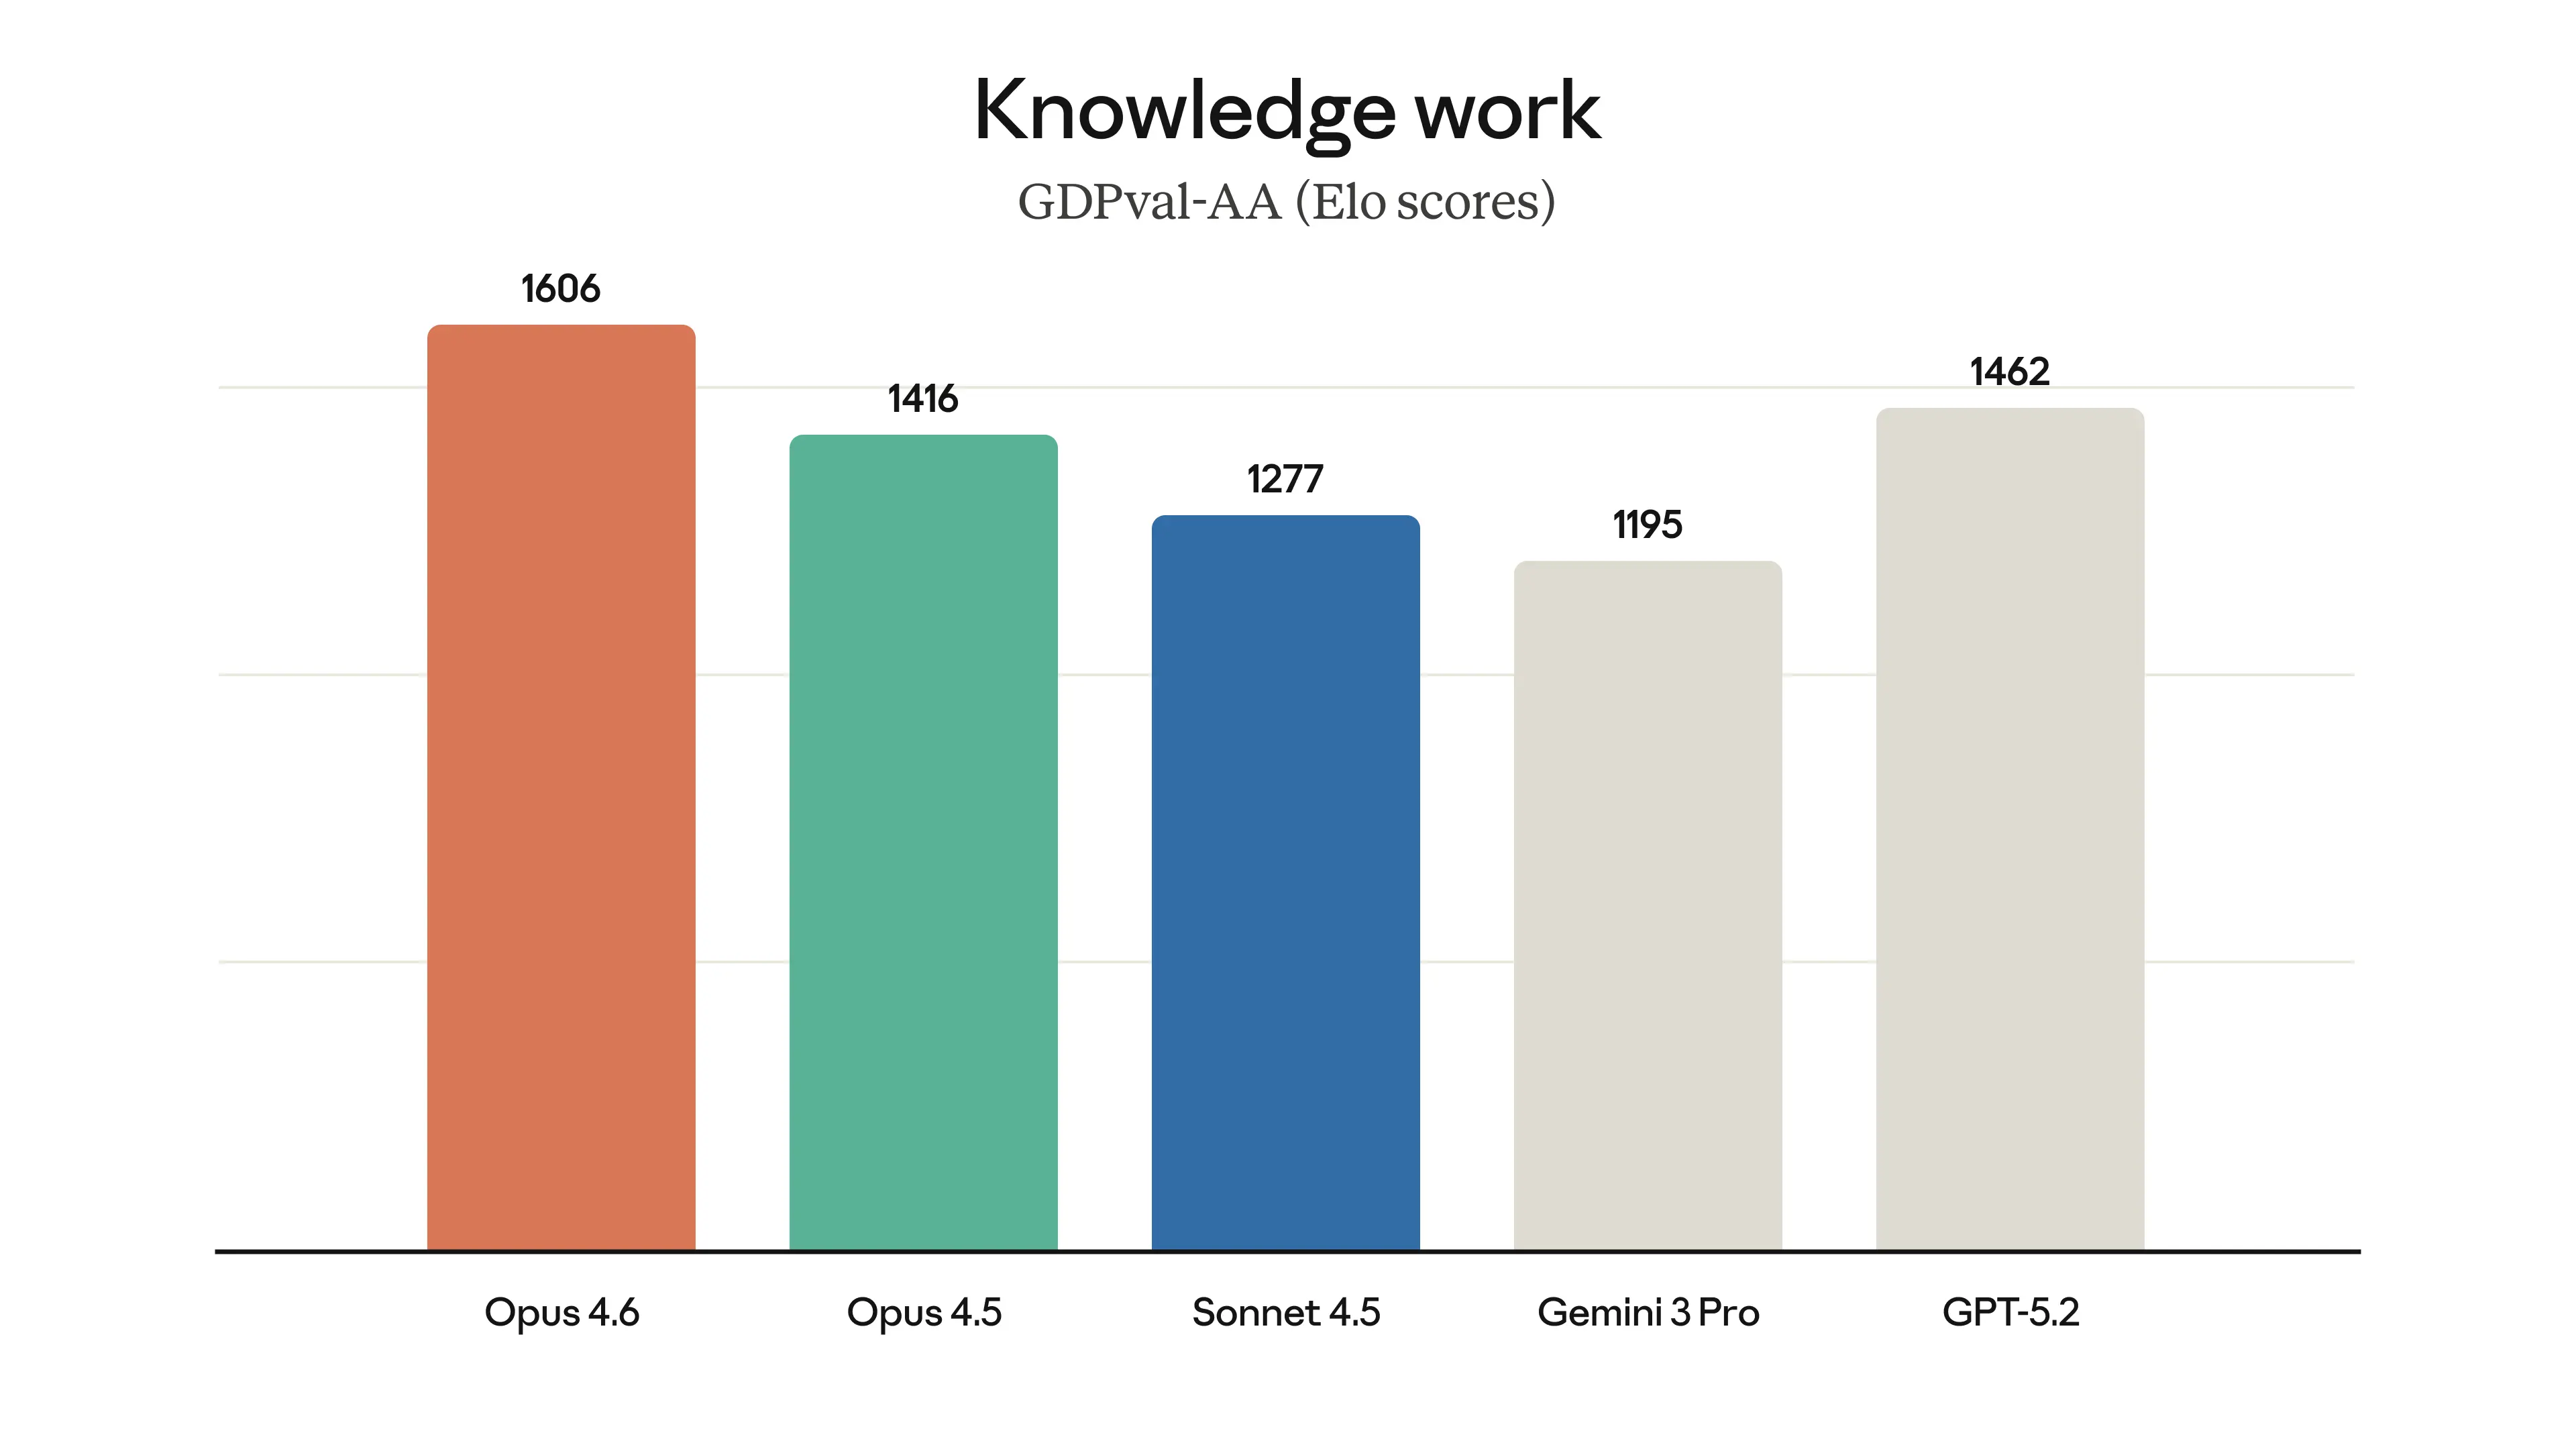
P.10EditorPickClaude Opus 4.6 adds agent teams, a 1 million token context window, and adaptive thinking, with benchmark gains that put pressure on OpenAI and Google.
Anthropic used Super Bowl ads to pledge Claude will never show ads, contrasting itself with OpenAI's move to add sponsored suggestions to ChatGPT.
Anthropic launched domain-specific Claude Cowork plugins for legal, finance, sales, and marketing, with MCP integrations for Slack, Figma, and Salesforce.
Anthropic releases Claude Sonnet 5 codenamed Fennec with 82.1% SWE-Bench score, surpassing Opus 4.5. Optimized for Google's Antigravity TPU with 1M token context at $3/M input tokens.
Goldman Sachs partnered with Anthropic to build autonomous AI agents for accounting and compliance. Here's how they did it, what they learned, and what other enterprises can take from this deployment.
OpenAI and Anthropic released flagship coding models the same day. We compare GPT-5.3 Codex and Claude Opus 4.6 on benchmarks, pricing, and real coding tasks.
Claude Opus 4.6 found 500+ unknown zero-day vulnerabilities in open-source code, a milestone for AI-powered security research and what it means for developers.
Model Context Protocol is the new standard for connecting AI to external tools. Here's a practical guide to building, deploying, and debugging MCP servers — with real code examples from production.
Architecture patterns, prompt engineering, cost control, and a production checklist for AI applications. The parts that outlast any given model.
GitHub Copilot vs Cursor vs Claude Code - which AI assistant actually saves you time? A practical comparison based on real-world testing and developer workflows.